
In brief: Aside from concerns about human extinction or a massive financial bubble, one of generative AI's biggest controversies is how tech giants train their models. While OpenAI and Microsoft claim that training AI on copyrighted material falls under fair use, internal comments from the companies could suggest otherwise.
Brent Hecht, Microsoft's director of applied science, predicted that people worldwide would view large language models as theft on an unprecedented scale, according to court documents released Thursday. The comments appear to counter Microsoft and OpenAI's public defense against an ongoing lawsuit brought by news outlets.
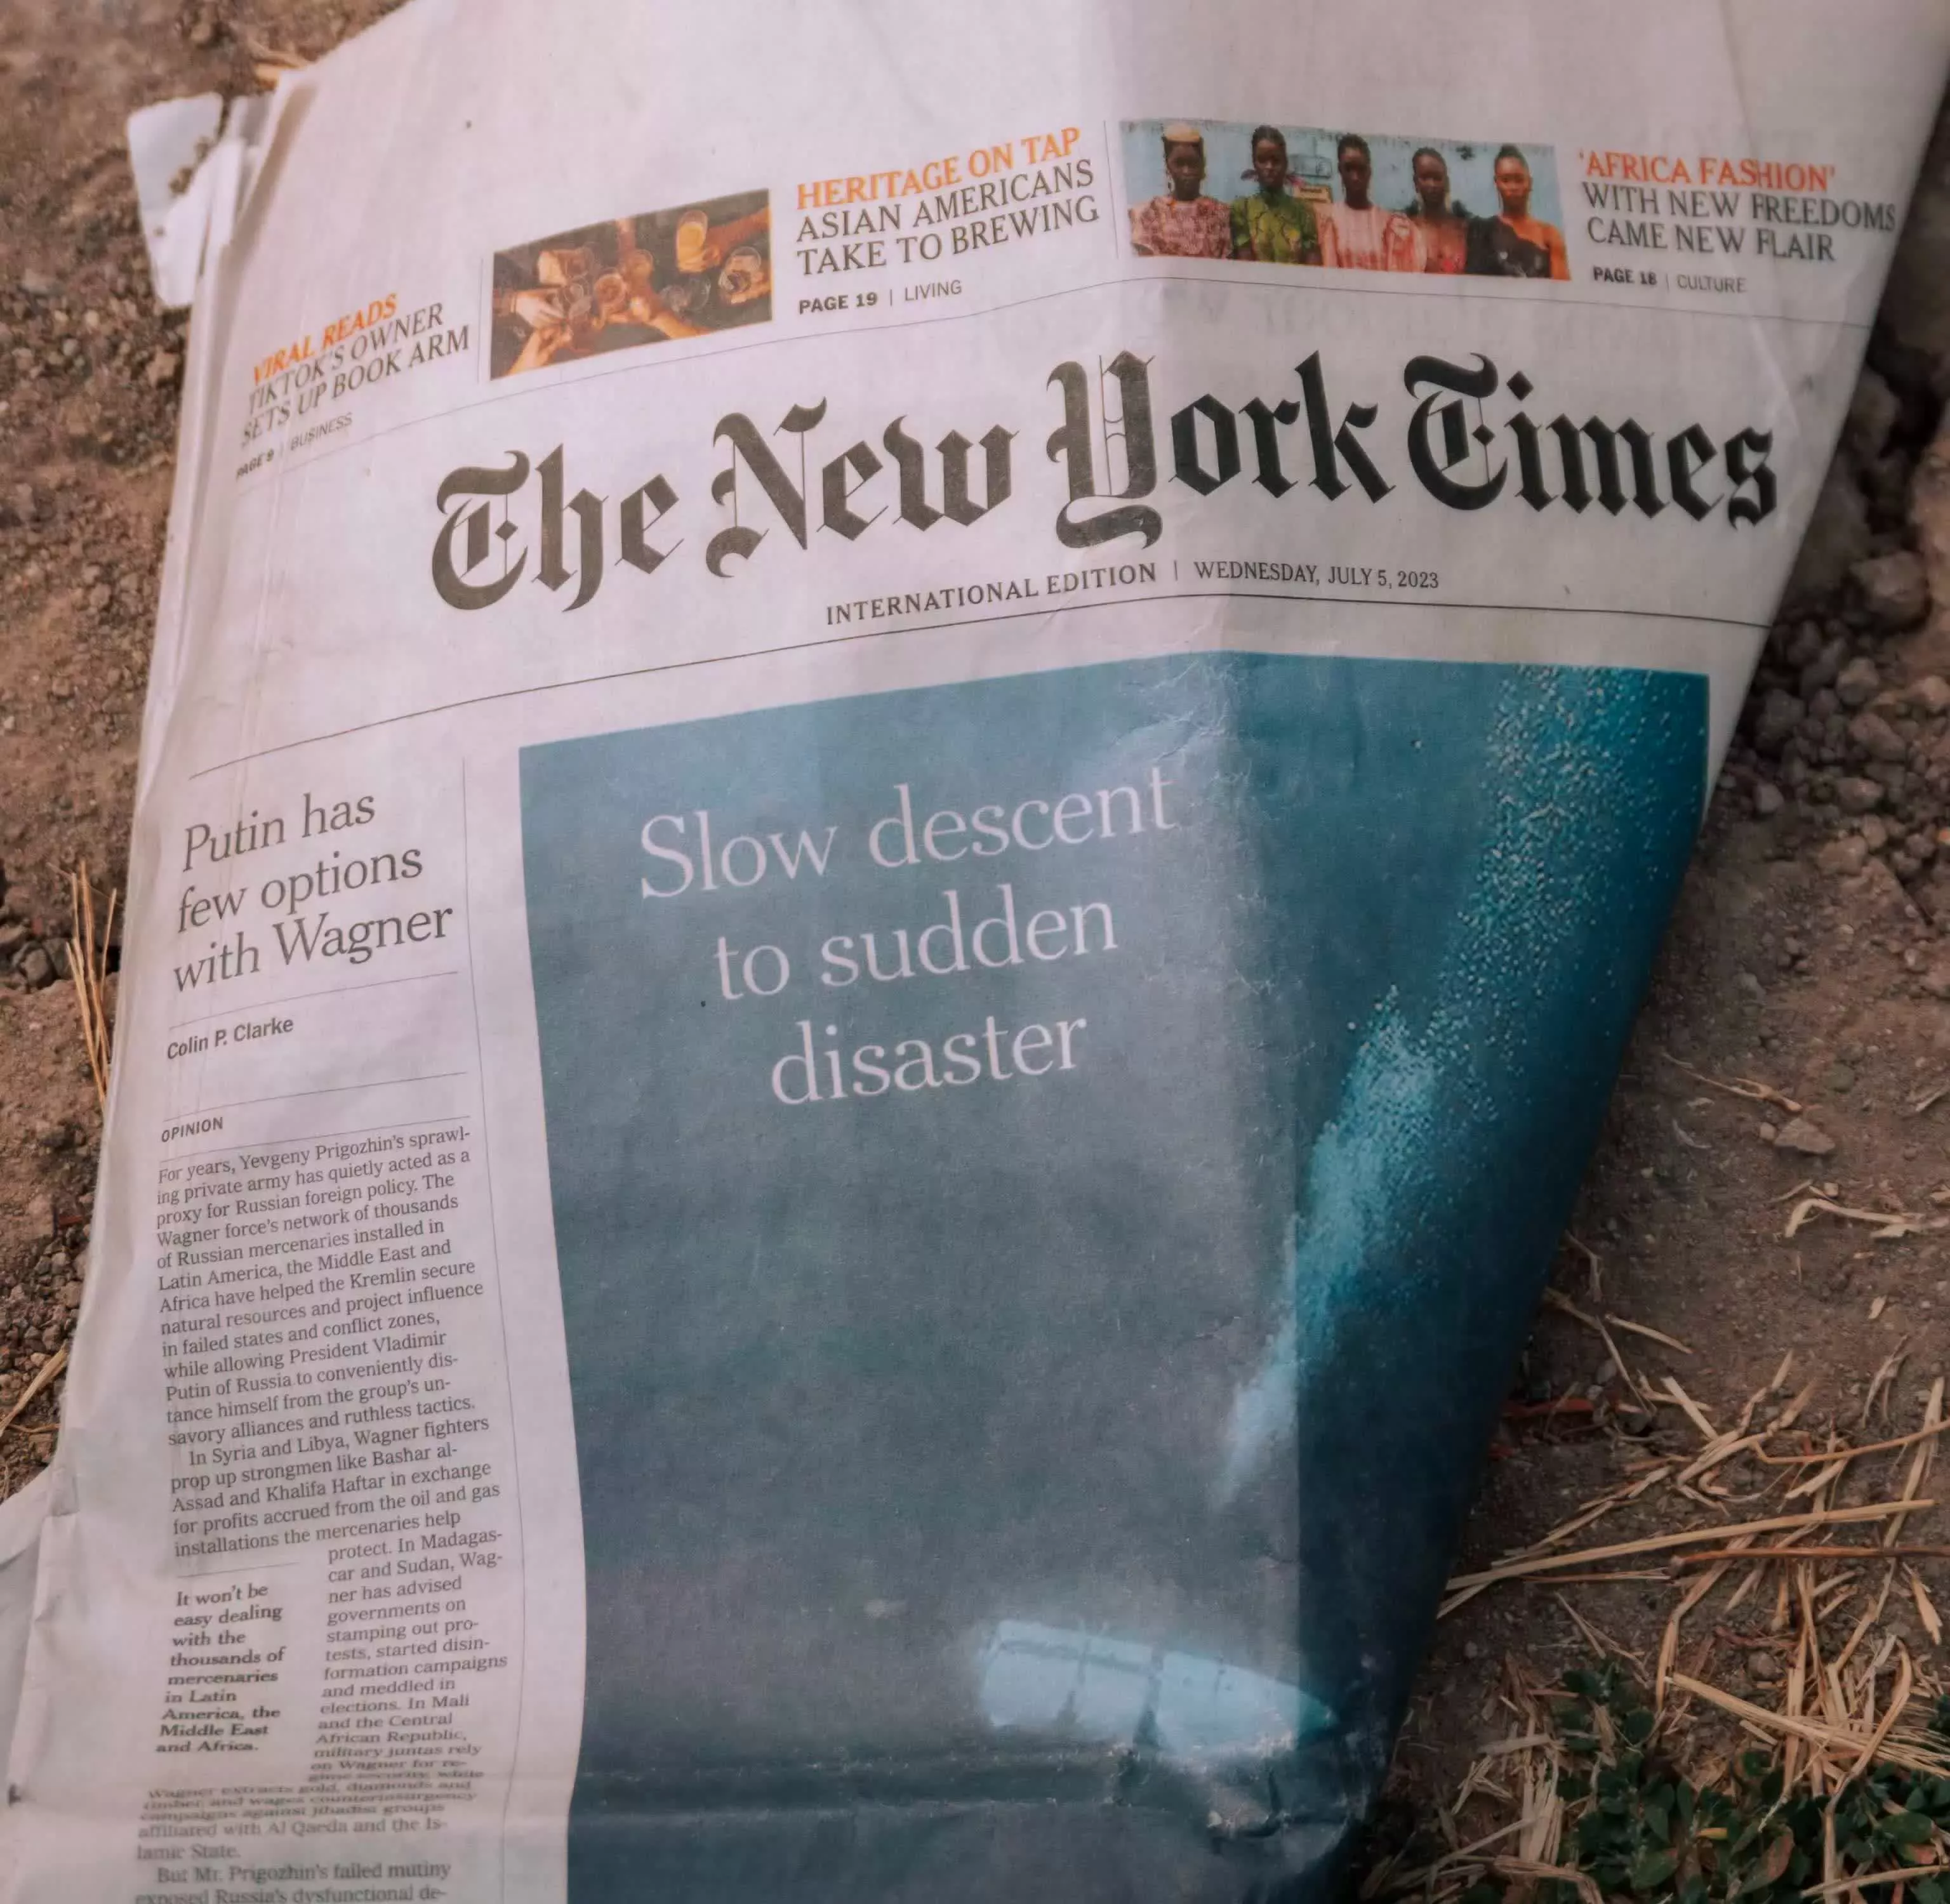
In the case's latest filing, Hecht said generative AI could be the largest labor theft in human history while describing how Microsoft, OpenAI, and other AI companies train their models on massive amounts of material from the open internet. The practice lies at the heart of the copyright lawsuit that The New York Times filed in late 2023.
Microsoft and OpenAI argue that training AI models on articles from the NYT and other publications falls under fair use, similar to a student reading books. The defendants also claim that generative AI output based on those articles sufficiently transforms the original material.
However, Thursday's filing contains internal comments from OpenAI that highlight AI's ability to reproduce news articles. For example, OpenAI executive Greg Brockman admitted that ChatGPT can predict and complete sentences from NYT articles when working with the outlet's material. Hecht also argued that winning the lawsuit might require the defendants to "make a complete mockery of the idea of fair use."
OpenAI has also previously admitted that training AI without accessing copyrighted material is impossible. Former Meta executive Nick Clegg echoed that view last year, claiming AI would die almost immediately if copyright law were enforced against it.
Meanwhile, AI companies have continued training their models on reams of user data, articles, and other material. Meta drew controversy for training its AI on employee behavior, Microsoft's GitHub Copilot trains on user data unless users opt out, and Twitch only started allowing streamers to opt out after training on their material for years. AI developers are also quietly buying, scanning, and destroying millions of books to gather more training material.
Generative AI's impact on the news business model is another pillar of the NYT's lawsuit. Google and other search engines now provide AI-generated summaries of information from articles in response to user queries, potentially discouraging readers from visiting news websites. In this week's court filing, an OpenAI executive involved in ChatGPT's development said publishers face an existential threat from AI.